Closer to the Metal
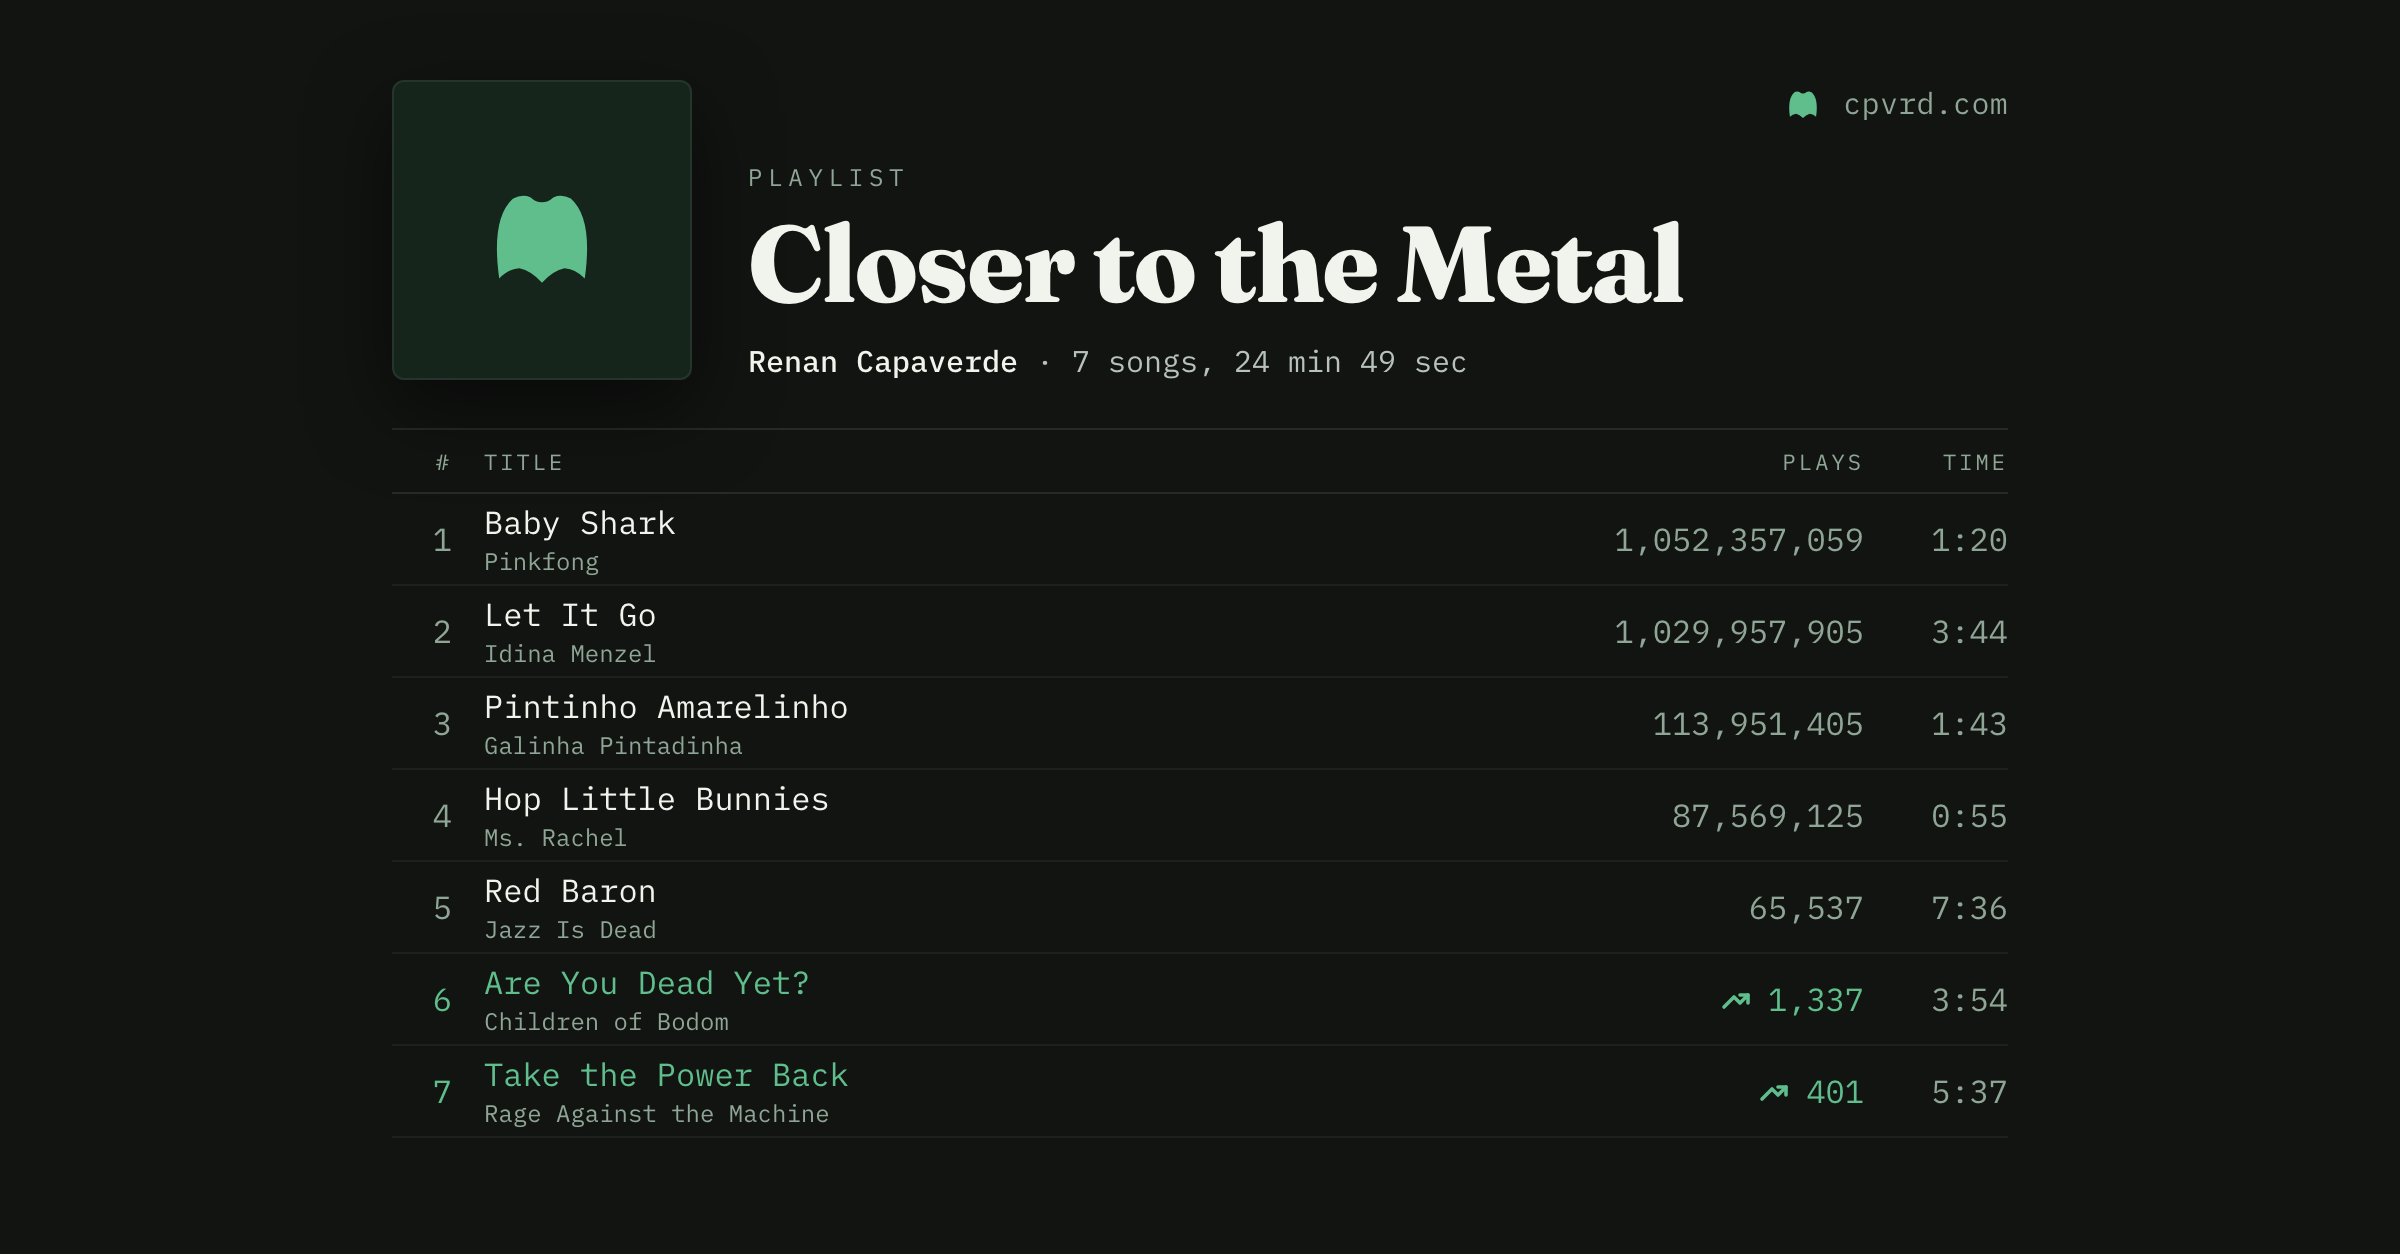
For more than twenty years I had long hair, and it is no secret that I am a metalhead. After my two kids were born, my playlists got closer to Baby Shark, Ms. Rachel and Galinha Pintadinha than to anything with a double bass pedal, so the title of this post is aspirational in that regard.
Jokes aside, if you are working at or investing in cloud infrastructure (and supply chain), be careful with how you provision future workloads. Software is getting closer to the metal, training won’t grow forever, and the AI race will end up with a couple of winners.
Since the early days of the AI rollercoaster, the doom around SaaS has been loud: the application layer is dead, SaaS is over, the agent eats the UI, and the software company is a thin wrapper waiting to be deleted unless it owns proprietary data and is the system of record. Some companies will die, but it was never going to be a mass funeral. The application layer is being rebuilt by incumbents and new players, and as it is rewritten, many will go for latency, performance and cost, with better abstractions moving up to the prompt and leaner runtimes underneath.
Before vibe coding was a thing, many programmers used higher-level languages to move faster in product development and correctness, often at the expense of performance. As the abstraction layer for programming moves from the programming language into the prompt, the runtimes and languages will often be picked by performance profiles and how good they are for agentic development.
At the same time, it is obvious that we are in a general compute boom. The frontier labs are training, everybody is inferring, and a whole generation of vibe-coded companies is running code that is very unoptimized for performance, cost and scale, but very optimized for PMF velocity and scaling adoption.
The financing of all that is nothing but insane, with big tech, big chip and big cloud kinda trading cash for equity in the future valuations of the big labs, and selling subsidized tokens to everyone else.
OpenAI closed the biggest private raise in history this spring, is back for more at a much higher price before the year is out, and is racing Anthropic to the public markets. Bullish on the big ceiling, are we dead yet?
Now suppose the race settles sooner than the capex assumes, with open models closing the gap behind the winners. What does that do to all the silicon that was bought for the race?
Nobody wins a price war, but the playbook has always been to play the price war with VC money, earn big scale adoption, and then enjoy the monopoly/cartel structure and start extracting the profits.
What I really have to ask is: who is making a profit right now? How can open models be so good? Who is paying for them? It kinda feels like Big AI is running a Ponzi scheme, or circular financing if you want to be polite: a cost war instead of a price war, with the cost financed by Big Cloud and Big Chip.
We have seen this movie, and it doesn’t end well for the main cast (tu-dum-psh). Between 1998 and 2001 the telecoms laid far more fiber than anyone could use, by 2002 Global Crossing and WorldCom had gone bust, and the dark fiber they left behind made bandwidth nearly free.
YouTube, Netflix and others were built on the losers’ capex. The competitors all lost and the future generations and companies reaped the benefits of that cost war. Similarly, when the training race settles, GPUs won’t disappear, they will just get cheaper, even if they age faster than fiber and need a power line to be worth anything.
This time is different, I hear: demand first, capex paid in cash instead of junk bonds. Fair, but how much of that demand exists without the subsidized tokens?
In the previous decades, “Intel made chips faster and Microsoft made the software slower” while many midsized-to-large companies heavily tuned database performance because the workload needed to fit in the box they had. Years later, with the cloud, sysadmins and DevOps engineers decided it was easier to upgrade from a 2xlarge to a 4xlarge instance than to talk to the Dev team.
But, when the cost to change dramatically reduces and there is less hand-off involved in the process, more changes come, in languages, platforms, hardware, stateful components and architecture.
ScyllaDB rebuilt Cassandra from Java into C++ for 10x the throughput, and it took a company and years. Many others rewrote the runtime instead, like Facebook famously did for PHP with HHVM and Google for JavaScript with V8, and got a few x too.
Now Astral rewrote the Python tooling in Rust and got somewhere between 10x to 100x, and Mojo launched initially as a Python superset with semantics inspired by Rust and performance from being built on MLIR. I think Mojo is super interesting as it gets closer to the metal using one of the most popular programming languages for vibe coding as its basis, combining performance and access.
At Nubank, we moved from native iOS and Android to Flutter to avoid paying the development and maintenance cost twice and the tax of managing feature parity and potentially divergent products in the codebase. Almost a decade later, DHH announced six native apps from a tiny team as all the aforementioned costs got much cheaper now.
The cloud never sold cheap hardware, it sold Opex instead of Capex with reduced complexity and people cost, and that is why many moved their datacenters there. A few moved back, like Dropbox, because almost all their value prop was based on storage.
A friend told me over lunch in San Francisco, unprompted: “I hate the cloud, I love bare metal”, and he is not alone. Oxide had the foresight and is a couple of years ahead of what is coming, and TinyCorp is after the same idea from the other end, a box on your desk instead of a rack in your datacenter.
Windows servers to Linux happened everywhere (pushed by licenses, security concerns and management simplicity). Amazon spent years getting its own business off Oracle and only turned off the last database in 2019.
Most veterans in software engineering know that optimizing the runtime, bits and bytes, matters less than fixing a bad architecture. Vibe coding is about to produce a big wave of bad architectures that will demand more capacity, not less, and the naive vibe coder often ends up with something less optimized than before, with a lot more people building that way. The difference now is that fixing the architecture and migrating to improve it got much cheaper too, without necessarily changing the runtime.
Truth is, they are all huge migrations that take a lot of intentional stubbornness to get to the finish line instead of letting the initiatives die off. Big migrations used to fail for lack of the discipline to persist through years of fatigue, headwinds and freaking Pareto.
I am a pragmatic guy and the 80/20 rule is useful for many many things, but definitely not for the long term. Do the math and you will see: 80/20 of 80/20 is 64/36 and 80/20 of that is 51/49.
Renan’s law: stack enough Pareto and you lose your edge.
So compute eventually gets cheaper and, with the last 20% finally affordable, switching gets cheaper at the same time, and those vibe-coded companies are next in line to migrate. Sure, the freed compute gets used, but by workloads that would never pay training prices.
Once applications get rebuilt and get more performant, fewer machines are used for these workloads. Some of it becomes inference workload and some is used for other companies being built, probably not a big problem for the clouds, which own most of the hardware that will be left over and can sell it below cost for a long time.
The hardest landing is the chips. Training and big inference use thousands of chips wired into one machine, with a premium mark-up. Common inference, already the bigger share of the load and growing, and other everyday workloads run fine on commodity and custom silicon, but if the race settles this way, the company whose valuation skyrocketed by selling premium GPUs feels it the most (scenario, not forecast, and definitely not financial advice).
Of course, the alternative case is that training doesn’t settle, inference explodes and workloads get heavier and heavier because more people vibe code poorly performing software. The limit on that scenario is not necessarily chips, but available power (not energy).
Jazz is dead, but metal is not. Chips are not cheap and I love Baby Shark. Don’t let it go, take the power back.